Test every prompt change on real cases before it ships.
500 runs a month free. No card.
Cases from real traffic, not a spreadsheet
Pull conversations from production traces or a read replica. Tag them, keep a golden set, and let it refresh every night so your tests track what customers ask this month.
app.fenwick.run/datasets

app.fenwick.run/prompts
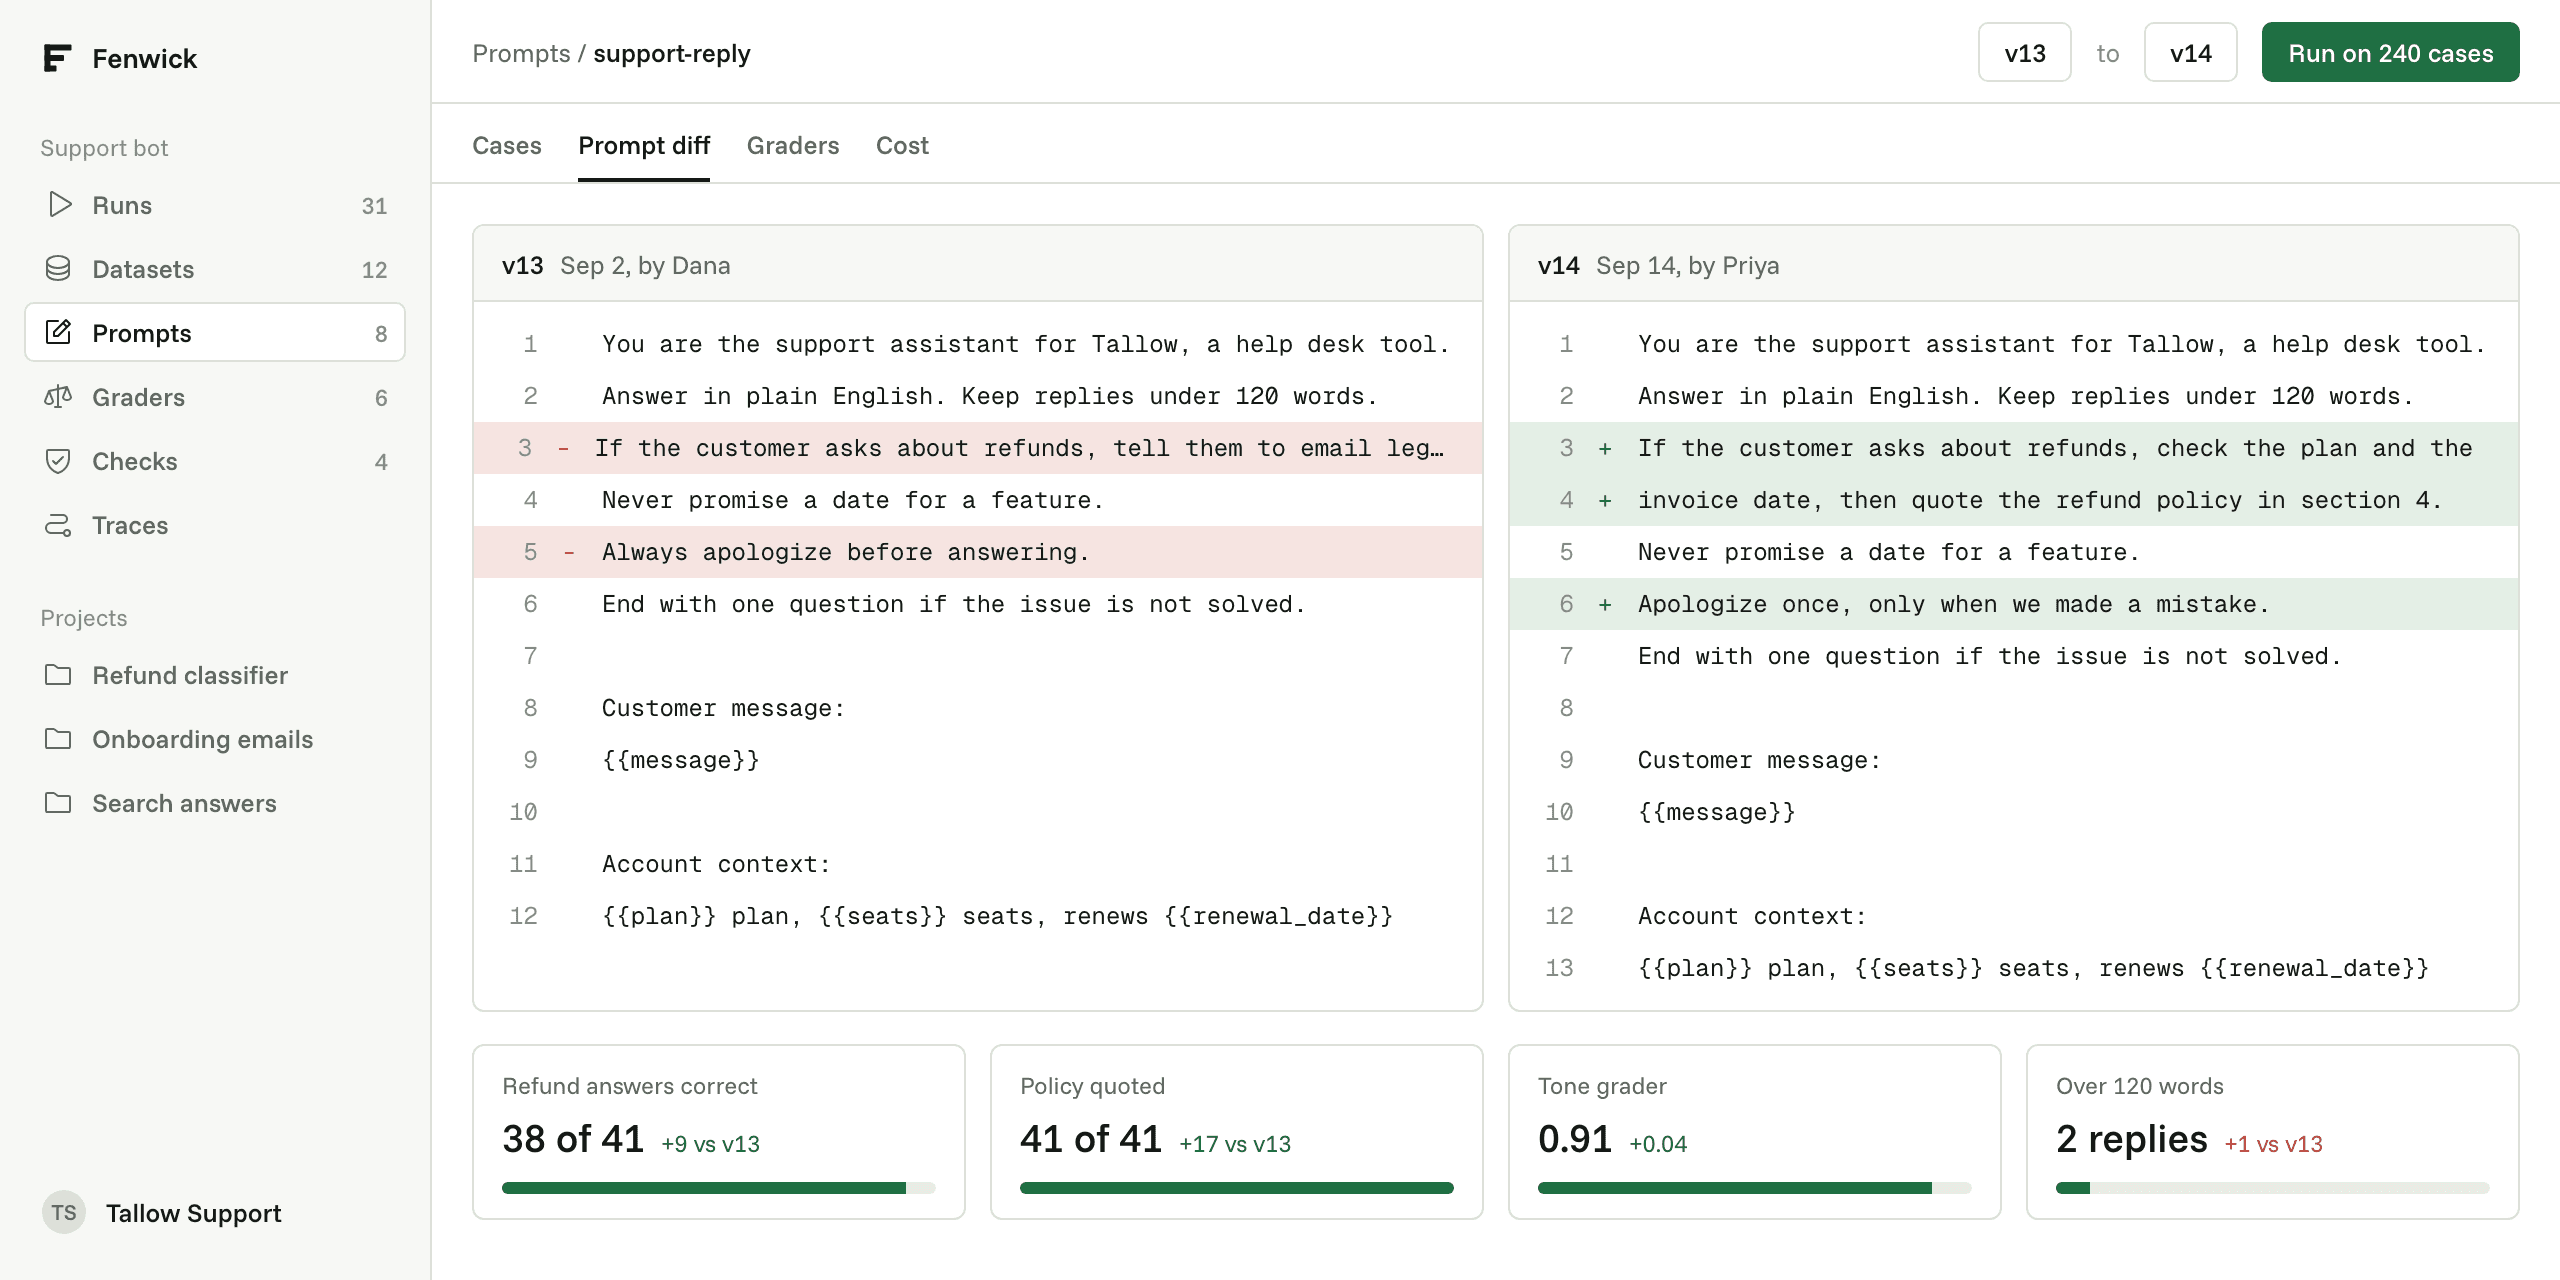
See which answers changed, and why
Put two prompt versions side by side. Every case shows both outputs, the grader scores and a one-line note on what moved.
A red check when quality drops
Fenwick runs the suite on every pull request that touches a prompt. Set the bar once and the merge waits when pass rate or cost crosses it.
app.fenwick.run/checks

app.fenwick.run/traces

Every bad answer becomes a test
Production traces show each retrieval, model call and grader with its time and cost. Add any trace to a dataset in one click.
Set up in an afternoon
Most teams have their first comparison running before lunch and the pull request check on by the end of the day.
Connect your model keys and repo
Add an API key for each provider you call and install the GitHub app on the repo that holds your prompts. Keys stay encrypted in your workspace.
Import 200 real cases
Pull recent conversations from traces, a CSV or a Postgres query. Tag the ones that matter and mark a golden set.
Run it, then turn on the check
Compare your current prompt with the next one. When the numbers look right, set a pass bar and every pull request gets checked.







What changed for teams that test first
“Moving our ticket tagger to a smaller model took one afternoon of runs instead of two weeks of arguing. The bill for tagging dropped to a third.”
Luis Ortega
Staff engineer at Parcelwise, shipping software, Columbus
“Reviewers actually read prompt pull requests now, because the comment shows ten changed cases instead of a wall of text.”
Amara Nwosu
Engineering manager at Ledgerline, billing for clinics, Atlanta
Shipped lately
A release most weeks. Every change is written up in plain English, with what it means for your runs.
Gate rules on cost, not just quality
Pull request checks can now fail when cost per request rises more than a limit you set.
New
Datasets refresh on a schedule
Point a dataset at a query or a trace filter and it refreshes every night.
New
Faster side by side diffs
Prompt diffs now load in under a second on runs with 2,000 cases.
Improved
Linear integration
Send failing cases to Linear with both outputs and the grader note attached.
New
Questions before you connect real data
Something else? Write to hello@fenwick.run and an engineer answers within one business day.
Do you train models on our data?
Can we keep everything inside our own cloud?
What counts as a run?
Which models and frameworks work?
What happens if we go over our runs?
Can we leave and take our data with us?
Run your next prompt change against 200 real cases this afternoon.
Free for 500 runs a month. Team from $39 a seat.