Datasets, diffs, checks and traces for LLM features
Four tools that share one set of real cases. Use them together, or start with the one that hurts most today.
Cases from real traffic, not a spreadsheet
Pull conversations from production traces or a read replica. Tag them, keep a golden set, and let it refresh every night so your tests track what customers ask this month.
Production traces, CSV or JSON, a Postgres query, or cases typed by hand.
Pin the cases that must always pass. They run first and can block on their own.
Every refresh keeps a snapshot, so a run from June replays exactly.

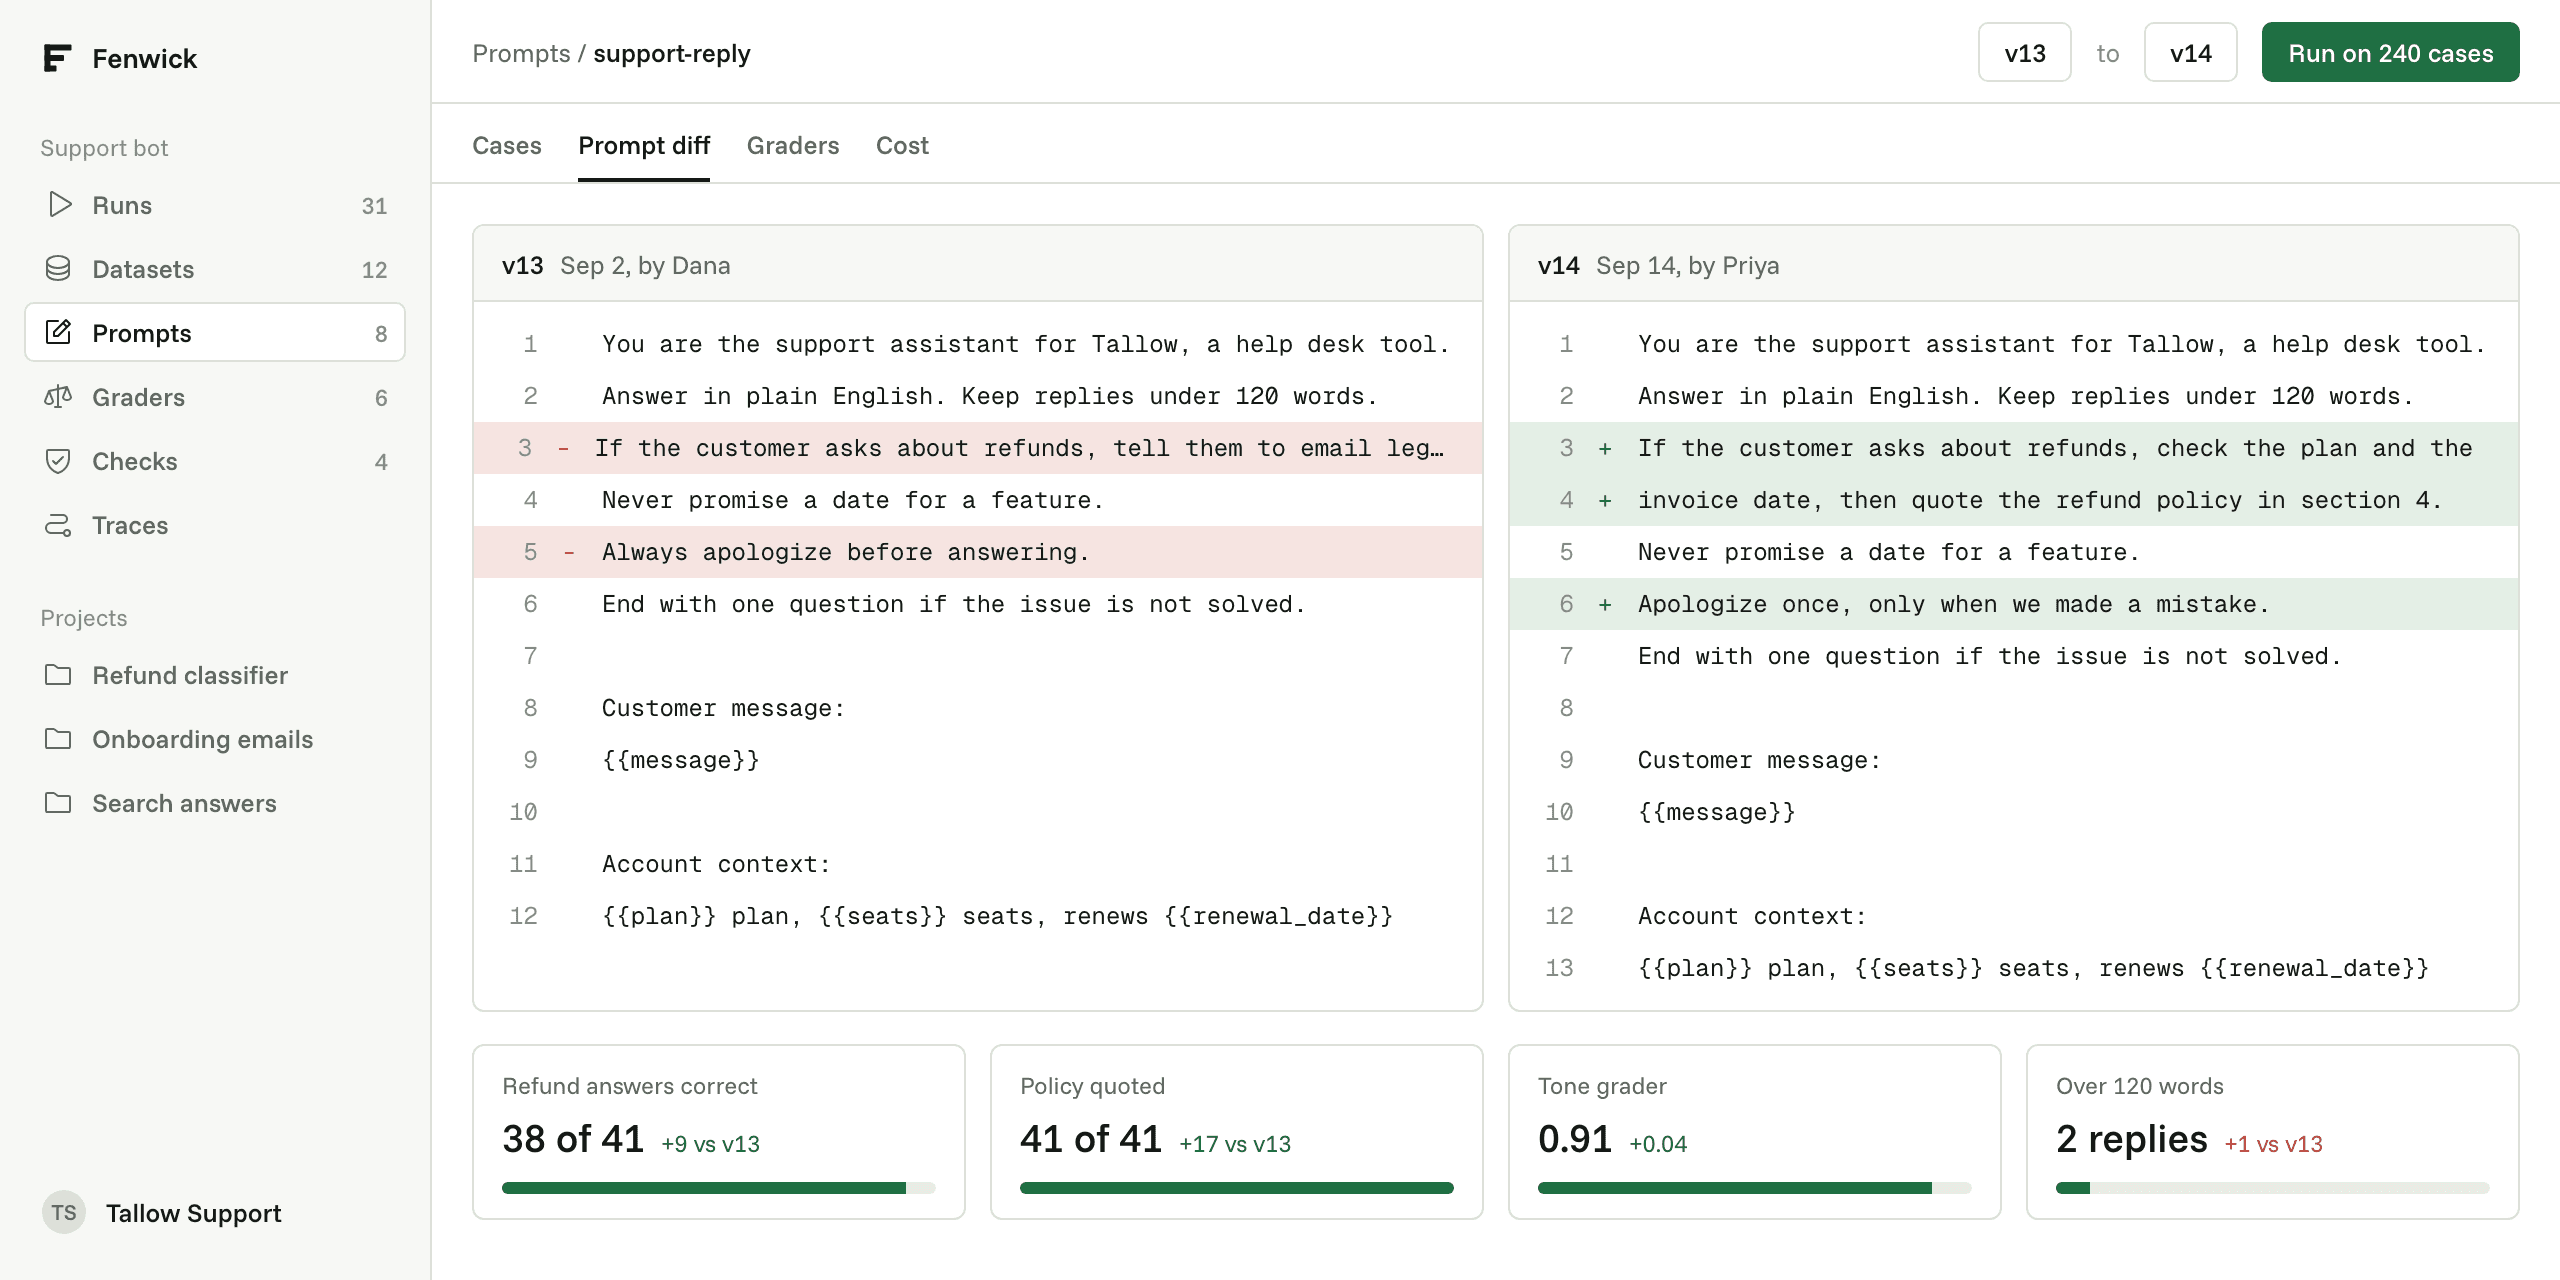
See which answers changed, and why
Put two prompt versions side by side. Every case shows both outputs, the grader scores and a one-line note on what moved.
Both outputs for every case, with the changed sentences marked.
Exact match, JSON schema, regex, or a model grader that writes a one-line note.
Tokens, dollars and time per case, next to the quality score.
A red check when quality drops
Fenwick runs the suite on every pull request that touches a prompt. Set the bar once and the merge waits when pass rate or cost crosses it.
Pass rate, golden set, cost and latency limits, each with its own threshold.
Ten flipped cases in the pull request comment, with a link to the rest.
A reviewer can approve a failing check with a written reason, kept in the log.


Every bad answer becomes a test
Production traces show each retrieval, model call and grader with its time and cost. Add any trace to a dataset in one click.
SDKs for TypeScript and Python, plus OpenTelemetry. About 2 ms of overhead.
Filter by customer, prompt version, grader score or cost.
Any trace becomes a tagged test case in one click.
Run your next prompt change against 200 real cases this afternoon.
Free for 500 runs a month. Team from $39 a seat.